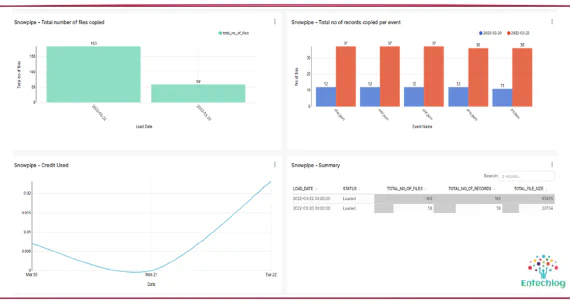
Visualizing Snowpipe usage with dbt and Superset
Snowpipe is Snowflake’s continuous data ingestion service. Snowpipe loads data within minutes after files are …


Picture this: you’ve been on a Snowflake account for two years. There are 47 databases, 180 schemas, and 12 service accounts. A new analyst joins and asks: “which DB is dev?” Nobody knows for sure. The dbt role can write to PROD. Half the warehouses are named after the team that built them. An audit lands and you spend three days mapping which roles read which data.
Every one of those problems has the same root: there’s no naming convention.
This article is the convention I wish I’d written down on day one. It covers account-level objects (users, roles, warehouses, databases), schema-level objects (tables, views, dynamic tables, policies, etc.), and the role architecture (Access Roles / Functional Roles / Service-Functional Roles) that makes the whole thing scale.
Before picking individual names, decide how the prefix is ordered. There are two common shapes:
| Shape | Example | Sorts/groups by | Best for |
|---|---|---|---|
| ENV-first | DEV_ENTECHLOG_RAW_DB, STG_ENTECHLOG_RAW_DB |
Environment | Single-project / single-product orgs - everything DEV groups together in Snowsight |
| PROJECT-first | ENTECHLOG_DEV_RAW_DB, ENTECHLOG_STG_RAW_DB |
Project / product | Multi-project shops where each team owns a slice - all ENTECHLOG objects group together |
Some enterprises add an additional organization prefix (e.g., ENT_) when they manage many products in a single account or anticipate acquisitions / data-sharing scenarios where collisions matter. For most setups this is optional.
This article uses ENV-first throughout. If your org has many domains in one account, swap to PROJECT-first - the rest of the patterns stay the same.
If you remember nothing else, remember these:
| What | Pattern | Example |
|---|---|---|
| Service user | [ENV]_[PROJECT]_[APP]_USER |
DEV_ENTECHLOG_DBT_USER |
| Access Role (read) | [ENV]_[PROJECT]_[LAYER]_RO_AR |
DEV_ENTECHLOG_DW_RO_AR |
| Access Role (write) | [ENV]_[PROJECT]_[LAYER]_RW_AR |
DEV_ENTECHLOG_DW_RW_AR |
| Functional Role | [PROJECT]_[JOB]_FR |
ENTECHLOG_ANALYST_FR |
| Service-Functional Role | [ENV]_[PROJECT]_[TOOL]_SVC_FR |
DEV_ENTECHLOG_DBT_SVC_FR |
| Warehouse | [ENV]_[PROJECT]_[ROLE]_WH_[SIZE] |
DEV_ENTECHLOG_DBT_WH_XS |
| Database | [ENV]_[PROJECT]_[LAYER]_DB |
DEV_ENTECHLOG_DW_DB |
| Schema | [GROUPING] (no prefix; DB is already env-scoped) |
HUBSPOT, DIM, FACT |
Three habits that make the rest fall into place:
The rest of the article expands each of these, plus all the object-by-object patterns.
In Snowflake, multiple environments are usually hosted in the same account. We use an environment prefix to differentiate them. Common environment prefixes:
DEV (and any of SIT, UAT, TEST, QA, STG as your promotion pipeline grows)CICDPRDALL (for the few objects that intentionally serve every env, like a user-facing query warehouse)The alternative to one-account-with-prefixes is separate accounts per environment. Stronger isolation, more operational complexity:
Pick separate accounts when isolation is a hard requirement (HIPAA / regulated data, hostile multi-tenant). Use one account with env-prefixed objects when isolation is a soft requirement.
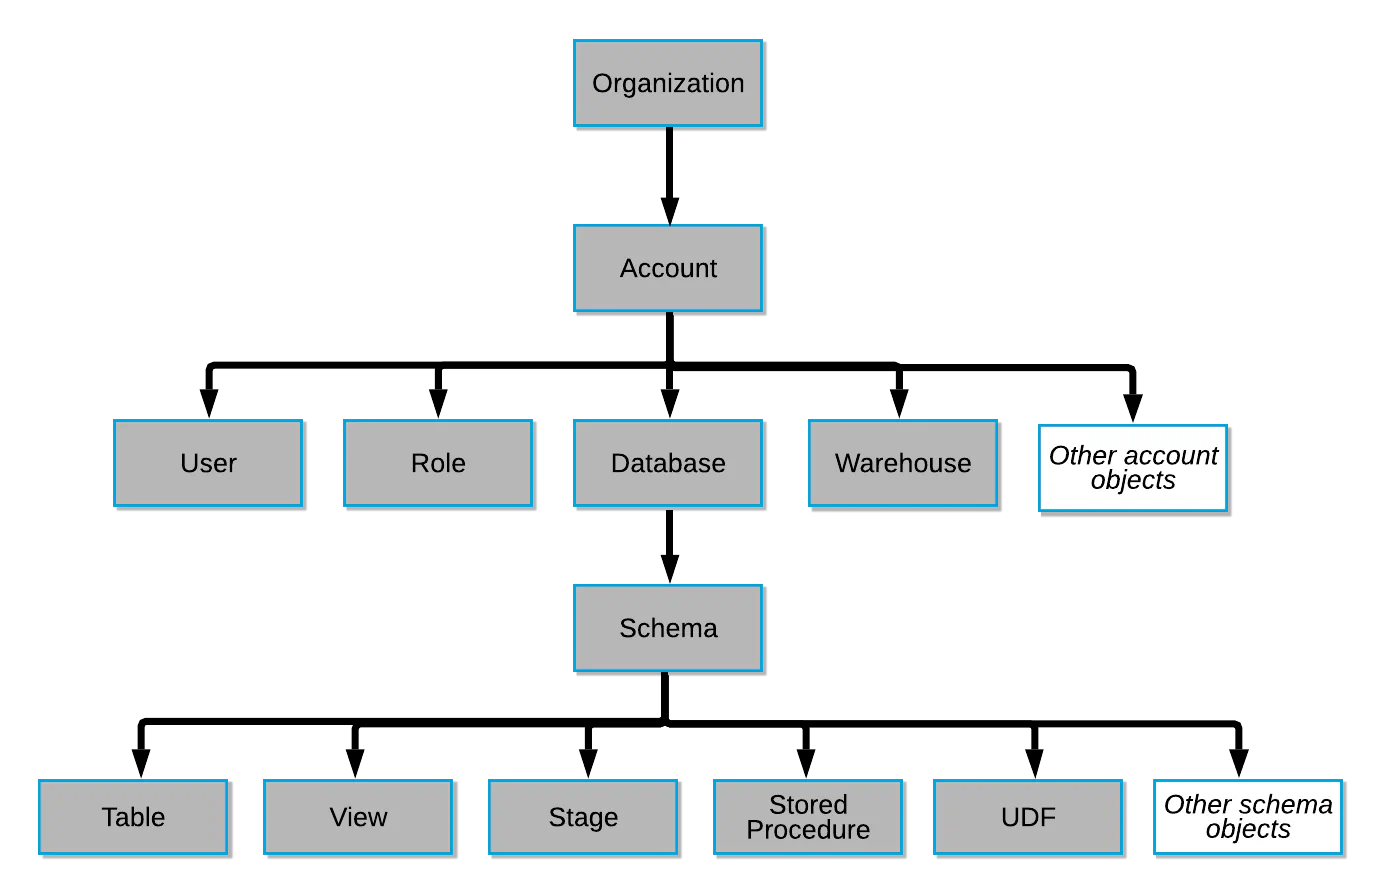
Before designing your own roles, know the ones Snowflake gives you:
| Role | Purpose | When to use it |
|---|---|---|
ACCOUNTADMIN |
Top-level - everything | Sparingly, for break-glass only |
SECURITYADMIN |
Manages users, roles, and grants | Most role/grant changes (issuing FUTURE grants, transferring OWNERSHIP) |
USERADMIN |
Creates and manages users + roles (but not grants on objects) | Provisioning new users |
SYSADMIN |
Owns objects (DBs, warehouses, schemas) | Creating DBs, warehouses |
PUBLIC |
Implicit - every user has it | Don’t grant anything sensitive to it |
Custom roles you build (AR / FR / SVC_FR below) should be granted to SYSADMIN so the SYSADMIN role hierarchy can manage the objects they touch.
User name is the unique identifier for the user in Snowflake. It is not the user’s login name (the name the user enters when logging in) - Snowflake allows users to have different user names and login names if desired.
There are two kinds of user accounts: user accounts used by real people, and service accounts used by system integrations.
| Naming Rule | [EMAIL] |
|---|---|
| Description | Prefer email address - unique within an organization, integrates cleanly with SSO/SCIM |
| Example | user@example.com |
| Required Privilege | USERADMIN |
| Naming Rule | [ENV]_[PROJECT/PROGRAM]_[APP_CODE]_USER |
|---|---|
| Description | Environment prefix, project/program short code, application short code, then _USER postfix |
| Example | DEV_ENTECHLOG_ATLAN_USER |
| Required Privilege | USERADMIN |
TYPE = SERVICE when creating service users. Snowflake forbids password / MFA / browser auth on TYPE = SERVICE users - they must use key-pair auth, OAuth, or programmatic access tokens (PATs). This is the right hygiene for headless service accounts and avoids credential leakage via committed passwords. The older TYPE = LEGACY_SERVICE (which still allows passwords) exists as a migration path only - don’t pick it for new accounts.A mature Snowflake setup separates roles into three layers. Each layer changes for one reason, so the blast radius of any one change stays small.
| Aspect | Flat (small setups) | Three-layer (AR / FR / SVC_FR) |
|---|---|---|
| Total roles for 3 DBs × 3 jobs × 3 envs | ~9 (one per job per env) | 18 ARs + 3 FRs + 3 SVC_FRs/env |
| Adding a new DB | Edit grants on every role that should see it | Create 2 ARs (RO + RW) with FUTURE grants, grant them to relevant FRs |
| Adding a new user | Grant the per-project role to the user | Grant the FR to the user - one statement |
| FUTURE grants | Hard to fit cleanly; you usually re-grant per object | Natural fit - they live on the AR, everything else inherits |
| Audit “who reads PRD finance data?” | Grep grants per role | SHOW GRANTS OF ROLE PRD_FINANCE_DW_RO_AR lists the FRs / SVC_FRs that hold it - one hop to the users |
Flat is fine when you have ~3 roles total. Switch to three-layer the moment you have more than one team or more than one tool integration.
flowchart TB
    USER["👤 admin@example.com"] -->|"granted"| FR["ENTECHLOG_ANALYST_FR
functional role, no env"]
    FR -->|"composes"| AR1["DEV_ENTECHLOG_DW_RO_AR"]
    FR --> AR2["STG_ENTECHLOG_DW_RO_AR"]
    FR --> AR3["PRD_ENTECHLOG_DW_RO_AR"]
    AR1 --> FUTURE["FUTURE grants on the database:
USAGE on FUTURE SCHEMAS
SELECT on FUTURE TABLES / VIEWS / DYNAMIC TABLES
(set once, applies to every new object)"]
    AR2 --> FUTURE
    AR3 --> FUTURE
    FUTURE --> OBJ["Every table / view / dynamic table
auto-inherits the AR's privileges"]
    classDef user fill:#fff2cc,stroke:#d6b656,color:#000
    classDef fr fill:#dae8fc,stroke:#6c8ebf,color:#000
    classDef ar fill:#d5e8d4,stroke:#82b366,color:#000
    classDef future fill:#fff4d6,stroke:#d6b656,color:#000
    classDef obj fill:#f8cecc,stroke:#b85450,color:#000
    class USER user
    class FR fr
    class AR1,AR2,AR3 ar
    class FUTURE future
    class OBJ obj
For service accounts the same shape, just with SVC_FR in the middle:
flowchart LR
    SU["🤖 DEV_ENTECHLOG_DBT_USER"] --> SVCFR["DEV_ENTECHLOG_DBT_SVC_FR
service-functional role, per env"]
    SVCFR --> RAW["DEV_ENTECHLOG_RAW_RO_AR"]
    SVCFR --> PREP["DEV_ENTECHLOG_PREP_RW_AR"]
    SVCFR --> DW["DEV_ENTECHLOG_DW_RW_AR"]
    classDef svc fill:#fff2cc,stroke:#d6b656,color:#000
    classDef fr fill:#dae8fc,stroke:#6c8ebf,color:#000
    classDef ar fill:#d5e8d4,stroke:#82b366,color:#000
    class SU svc
    class SVCFR fr
    class RAW,PREP,DW ar
| Layer | Naming | Granted to | Holds |
|---|---|---|---|
Access Role (_AR) |
[ENV]_[PROJECT]_[LAYER]_RO_AR[ENV]_[PROJECT]_[LAYER]_RW_AR |
Other roles only - never users | The actual privileges (USAGE on DB, FUTURE grants on schemas / tables / views) |
Functional Role (_FR) |
[PROJECT]_[JOB]_FR (no env - spans all envs via composed ARs) |
Human users | Other ARs |
Service-Functional Role (_SVC_FR) |
[ENV]_[PROJECT]_[TOOL]_SVC_FR |
Service users (one per tool, per env) | Other ARs |
If your org has 1-3 service integrations and 1-2 user job types, the flat pattern is fine. It’s the older shape Snowflake users were on before the AR/FR split crystallized:
| Naming Rule | [PROJECT/PROGRAM]_[ROLE_NAME]_ROLE |
|---|---|
| Description | Project/program short code, the role a user will play, then _ROLE postfix |
| Example | ENTECHLOG_ANALYST_ROLE ENTECHLOG_DEVELOPER_ROLE ENTECHLOG_DBT_ROLE |
| Required Privilege | USERADMIN |
I’ve seen each of these in production. Each one cost a team somewhere between a Friday afternoon and a rollback at 2am.
SECURITYADMIN and a single platform deployer.GRANT ROLE RO_AR TO ROLE RW_AR and add only the write-specific privileges to the RW_AR. Saves you from a “we only granted SELECT on three tables” audit miss.This is the single most-important hygiene grant in the role layer:
USE ROLE SECURITYADMIN;
GRANT ROLE ENTECHLOG_ANALYST_FR TO ROLE SYSADMIN;
GRANT ROLE DEV_ENTECHLOG_DBT_SVC_FR TO ROLE SYSADMIN;
Why: without this, objects created by your custom FR / SVC_FR cannot be managed by SYSADMIN or ACCOUNTADMIN. You end up needing the original custom role to drop or alter the object, which is brittle and lock-out-prone.
Database roles are roles scoped to a single database. They can only be granted privileges within that DB and can themselves be granted to account-level roles. Useful when you want to package privileges with a database (e.g., a shared inbound database from a Snowflake Share comes with database roles attached). For most internal RBAC, account-level ARs are simpler and easier to reason about.
Once the AR layer is in place, FUTURE grants are what make it scale. Without them, every new table created requires a fresh GRANT SELECT ON TABLE … to every role that should see it. With them, you set the grant once on the access role at the database level, and Snowflake applies it to every table created afterwards.
USE ROLE SECURITYADMIN;

-- Read-only access role for the RAW database
CREATE ROLE IF NOT EXISTS DEV_ENTECHLOG_RAW_RO_AR;
GRANT USAGE ON DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;

-- FUTURE grants - covers anything created later
GRANT USAGE  ON FUTURE SCHEMAS            IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
GRANT SELECT ON FUTURE TABLES             IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
GRANT SELECT ON FUTURE VIEWS              IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
GRANT SELECT ON FUTURE DYNAMIC TABLES     IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
GRANT SELECT ON FUTURE EXTERNAL TABLES    IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
GRANT SELECT ON FUTURE MATERIALIZED VIEWS IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;

-- ALL grants - back-fill anything that already exists (no-op for a fresh DB)
GRANT USAGE  ON ALL SCHEMAS IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
GRANT SELECT ON ALL TABLES  IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
GRANT SELECT ON ALL VIEWS   IN DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE DEV_ENTECHLOG_RAW_RO_AR;
-- (etc.)

-- Now wire the AR into the FR - composable, single point of change
GRANT ROLE DEV_ENTECHLOG_RAW_RO_AR TO ROLE ENTECHLOG_ANALYST_FR;
GRANT ROLE ENTECHLOG_ANALYST_FR    TO ROLE SYSADMIN;
GRANT ROLE ENTECHLOG_ANALYST_FR    TO USER  "admin@example.com";
A read-write AR adds INSERT, UPDATE, DELETE, TRUNCATE, REFERENCES on FUTURE tables, plus CREATE TABLE / VIEW / DYNAMIC TABLE / TASK / … on FUTURE schemas.
-- Does the analyst actually have read on this DB via the chain?
SHOW GRANTS TO USER "admin@example.com";              -- should show ENTECHLOG_ANALYST_FR
SHOW GRANTS TO ROLE ENTECHLOG_ANALYST_FR;             -- should show DEV/STG/PRD RO_ARs
SHOW GRANTS TO ROLE DEV_ENTECHLOG_RAW_RO_AR;          -- current grants (incl. the ALL back-fill)
SHOW FUTURE GRANTS TO ROLE DEV_ENTECHLOG_RAW_RO_AR;   -- the FUTURE grants (SHOW GRANTS doesn't list them)
SHOW FUTURE GRANTS IN DATABASE DEV_ENTECHLOG_RAW_DB;  -- the same FUTURE grants, viewed from the object

-- Account-wide audit query (ACCOUNT_USAGE can lag by up to ~2 hours)
SELECT grantee_name, privilege, granted_on, name
FROM SNOWFLAKE.ACCOUNT_USAGE.GRANTS_TO_ROLES
WHERE grantee_name = 'ENTECHLOG_ANALYST_FR'
  AND deleted_on IS NULL;
GRANT … ON FUTURE requires the global MANAGE GRANTS privilege - owning the database is not enough. The only exception is a managed access schema, whose owner can define future grants inside it. Use SECURITYADMIN or a dedicated platform role - never a per-team service role.ALL and FUTURE clauses are independent: ALL TABLES covers what exists today, FUTURE TABLES covers what gets created tomorrow. Almost always issue both.GRANT … ON FUTURE TABLES does not cover future dynamic tables, materialized views, etc. Issue one statement per object type.ON FUTURE / ON ALL grants in definition files are slated for deprecation in favor of the newer INHERITED grants (preview at the time of writing).A virtual warehouse is a cluster of compute resources in Snowflake - CPU, memory, and temporary storage that runs queries, loads data, and performs DML.
DEFAULT_WAREHOUSE on each user, pointing at the warehouse for that user’s primary role. The payoff is clean per-warehouse cost attribution and clear blast-radius isolation.| Naming Rule | [ENV]_[PROJECT/PROGRAM]_[ROLE_NAME]_WH_[WH_SIZE] |
|---|---|
| Description | Environment prefix, project/program short code, the role that uses the warehouse, _WH_, then a size identifier (XS/S/M/L/XL/…) |
| Example | ALL_ENTECHLOG_ANALYST_WH_S ALL_ENTECHLOG_ANALYST_WH_M ALL_ENTECHLOG_ANALYST_WH_L DEV_ENTECHLOG_DBT_WH_S DEV_ENTECHLOG_DBT_WH_M DEV_ENTECHLOG_DBT_WH_L DEV_ENTECHLOG_DBT_WH_XL |
| Required Privilege | SYSADMIN |
User-facing roles (ANALYST) typically share their warehouses across envs (ALL_ prefix). System / service roles (DBT) get separate warehouses per env, so a runaway DEV query can’t impact a PRD batch cycle.
Resource monitors cap warehouse spending. One per warehouse (or one per group of warehouses) keeps the cost-control story simple.
| Naming Rule | [ENV]_[PROJECT]_[ROLE_NAME]_RM |
|---|---|
| Description | Mirrors the warehouse name but without size; suffix _RM |
| Example | DEV_ENTECHLOG_DBT_RM ALL_ENTECHLOG_ANALYST_RM |
| Required Privilege | ACCOUNTADMIN |
Most enterprises tie one resource monitor to all sizes of a warehouse (e.g., DEV_ENTECHLOG_DBT_RM caps DEV_ENTECHLOG_DBT_WH_S, _M, _L). When the cap trips, all sizes pause.
A database is a logical grouping of schemas.
| Naming Rule | [ENV]_[PROJECT/PROGRAM]_[DATA_LAYER]_DB |
|---|---|
| Description | Environment prefix, project/program short code, the data-layer name, then _DB postfix |
| Example | DEV_ENTECHLOG_RAW_DB DEV_ENTECHLOG_CONFORMED_DB OR DEV_ENTECHLOG_STAGING_DB OR DEV_ENTECHLOG_PREP_DB DEV_ENTECHLOG_CURATED_DB OR DEV_ENTECHLOG_DW_DB DEV_ENTECHLOG_SEMANTIC_DB OR DEV_ENTECHLOG_METRIC_DB |
| Required Privilege | SYSADMIN |
Layer naming is a team choice - RAW / PREP / DW is one common shape; BRONZE / SILVER / GOLD (medallion) is another; RAW / CONFORMED / CURATED is a third. Pick one and use it consistently across all envs and projects.
Integrations are account-level objects - they aren’t created in a database or schema, and CREATE INTEGRATION is granted on the account. They’re easy to misfile next to the stages and pipes that use them, so give them a clear type suffix. Avoid _STG_ for storage integrations: STG already means the staging environment and the stage suffix.
| Object Type | Naming Rule | Example |
|---|---|---|
| Storage Integration | [NAME]_STORAGE_INTG |
S3_RAW_STORAGE_INTG |
| API Integration | [NAME]_API_INTG |
GITHUB_API_INTG |
| Notification Integration | [NAME]_NOTIFY_INTG |
MOCKAROO_SQS_NOTIFY_INTG |
| Security Integration | [NAME]_SEC_INTG |
OKTA_SCIM_SEC_INTG |
| External Access | [NAME]_EXT_ACCESS_INTG |
OPENAI_EXT_ACCESS_INTG |
Outbound shares (you publish data) and inbound shares (you consume) have light naming.
| What | Naming Rule | Example |
|---|---|---|
| Outbound share | [PROJECT]_[CONSUMER]_SHARE |
ENTECHLOG_PARTNER_X_SHARE |
| Inbound DB | [PROVIDER]_[DATASET]_DB |
WEATHERSOURCE_HISTORICAL_DB |
As the consumer, you choose the database name when you run CREATE DATABASE … FROM SHARE (Marketplace pre-fills a provider-suggested name you can change). Pick one that matches the rest of your DB naming.
These govern how users authenticate and run sessions, not what data they touch. They’re applied to the account or to users, but only network policies are account-level objects. Password, session and authentication policies are schema-level objects, so keep them together in one admin database/schema (e.g. ADMIN_DB.POLICIES) rather than scattered across project databases.
| Object Type | Scope | Naming Rule | Example |
|---|---|---|---|
| Network Policy | Account | [NAME]_NP |
CORP_VPN_NP |
| Network Rule | Schema | [NAME]_NR |
CORP_VPN_NR |
| Password Policy | Schema | [NAME]_PP |
STRONG_PASSWORD_PP |
| Session Policy | Schema | [NAME]_SESS_POL |
EXEC_SESSION_SESS_POL |
| Authentication Policy | Schema | [NAME]_AUTH_POL |
SSO_ONLY_AUTH_POL |
Schema-level objects can use the same name across all environments - they live inside an env-prefixed database, so the path is unique. No env prefix needed on the object name. (The login and session policies above are the exception: they live in a shared admin schema, so their names should say which env or user group they apply to when that differs.)
| Naming Rule | [DATA_GROUPING] |
|---|---|
| Description | The grouping could be by source name, normalization technique, or modeling layer |
| Example | DEV_ENTECHLOG_RAW_DB.HUBSPOT DEV_ENTECHLOG_RAW_DB.SALESFORCE DEV_ENTECHLOG_PREP_DB.STAGING DEV_ENTECHLOG_DW_DB.DIM DEV_ENTECHLOG_DW_DB.FACT DEV_ENTECHLOG_DW_DB.OBT DEV_ENTECHLOG_DW_DB.SEMANTIC |
| Required Privilege | CREATE SCHEMA |
| Object Type | Naming Rule | Example |
|---|---|---|
| Table | [TABLE_NAME] | DEVICE |
| View | [VIEW_NAME] | ACTIVE_DEVICE |
| Materialized View | [NAME]_MV | DAILY_SALES_MV |
| Dynamic Table | [NAME]_DT | CUSTOMER_ORDERS_DT |
| Iceberg Table | [TABLE_NAME] | DEVICE (no suffix - Iceberg vs native is a storage detail visible via DESC TABLE) |
| External Table | [NAME]_EXT | S3_EVENTS_EXT |
| Hybrid Table | [TABLE_NAME] | SESSION (same as table - Hybrid is a storage detail) |
| Semantic View | [NAME]_SV | ORDER_STATS_SV |
| Object Type | Naming Rule | Example |
|---|---|---|
| File Format | [NAME]_[FORMAT]_FF | MOCKAROO_XML_FF |
| Stage | [NAME]_[TYPE]_STG | MOCKAROO_S3_STG |
| Snowpipe | [NAME]_PIPE | MOCKAROO_PIPE |
| Stream | [NAME]_STREAM | MOCKAROO_STREAM |
| Object Type | Naming Rule | Example |
|---|---|---|
| Stored Procedure | [NAME]_SP | MOCKAROO_SP |
| Function (UDF / UDTF) | [NAME]_UDF / [NAME]_UDTF | NORMALIZE_PHONE_UDF |
| Task | [NAME]_TASK | MOCKAROO_TASK |
| Alert | [NAME]_ALERT | PIPE_FAILURE_ALERT |
| Streamlit App | [NAME]_APP | SALES_DASH_APP |
| Cortex Agent | [NAME]_AGENT | SALES_AGENT |
| Object Type | Naming Rule | Example |
|---|---|---|
| Tag | [NAME]_TAG | PII_TAG, COST_CENTER_TAG |
| Masking Policy | [NAME]_MP | EMAIL_MASK_MP |
| Row Access Policy | [NAME]_RAP | REGION_FILTER_RAP |
Tags don’t just exist - they’re the cleanest way to attribute cost and discover PII across hundreds of objects. Tags are schema-level objects, so create them once in a shared admin schema and reference them fully qualified:
USE SCHEMA ADMIN_DB.TAGS;
CREATE TAG COST_CENTER_TAG COMMENT = 'Finance cost-center code';
CREATE TAG PII_TAG ALLOWED_VALUES 'NONE','LOW','MEDIUM','HIGH';
CREATE TAG OWNER_TAG COMMENT = 'Team or person responsible for the object';

-- Ownership / PII: tag once at the database; schemas and tables inside inherit unless overridden
ALTER DATABASE DEV_ENTECHLOG_DW_DB
    SET TAG ADMIN_DB.TAGS.OWNER_TAG = 'data-platform@example.com';

-- Cost: credits are spent by warehouses, so tag the warehouses
ALTER WAREHOUSE DEV_ENTECHLOG_DBT_WH_XS
    SET TAG ADMIN_DB.TAGS.COST_CENTER_TAG = 'CC1234';

-- Credits per cost center, last 30 days
SELECT t.tag_value          AS cost_center,
       m.warehouse_name,
       SUM(m.credits_used)  AS credits
FROM SNOWFLAKE.ACCOUNT_USAGE.WAREHOUSE_METERING_HISTORY m
JOIN SNOWFLAKE.ACCOUNT_USAGE.TAG_REFERENCES t
  ON  t.domain      = 'WAREHOUSE'
  AND t.object_name = m.warehouse_name
  AND t.tag_name    = 'COST_CENTER_TAG'
  AND t.object_deleted IS NULL
WHERE m.start_time >= DATEADD(day, -30, CURRENT_TIMESTAMP())
GROUP BY 1, 2
ORDER BY credits DESC;
This is one more reason for the one-warehouse-per-role rule: when every warehouse belongs to exactly one team, a warehouse tag is an exact cost attribution.
| Object Type | Naming Rule | Example |
|---|---|---|
| DCM Database | [ENV]_[PROJECT]_DCM_DB | DEV_ENTECHLOG_DCM_DB |
| DCM Project | [SCOPE] in a PROJECTS schema | DEV_ENTECHLOG_DCM_DB.PROJECTS.INFRA |
DCM PROJECT objects are env-scoped - one per env - but they don’t need an env prefix of their own: put each one in a dedicated [ENV]_[PROJECT]_DCM_DB and the database carries the env, just like any other schema object. Keeping project state in its own database also means a team’s deployment history lives next to nothing else.
DESC TABLE, and end users querying them shouldn’t care about the difference._SP is reused only by Stored Procedure here; Session Policy gets _SESS_POL to avoid collision.[NAME]_[TYPE] shape works - MY_APP_SVC for services and MY_APP_REPO for image repositories (both schema-level). Compute pools are account-level, so treat them like warehouses and give them an env prefix: DEV_ENTECHLOG_ML_POOL.When a single org has multiple Snowflake accounts across regions or clouds (AWS_USE1, AWS_EUW1, AZURE_EUW1, etc.), the cleanest pattern is account = region with NO region prefix on individual objects. Object names stay short; the account identifier tells you the region.
Snowflake SQL can’t query another account’s objects directly - data crosses accounts through replication or data sharing, and lands as a database in the consuming account. Keep the replica/shared database name identical to (or clearly derived from) the source, and let the account identifier (ORG-ACCOUNT) carry the region rather than encoding it in object names.
For a typical analytics project with three data layers and the three-layer role pattern, the names look like this:
Databases
  DEV_ENTECHLOG_RAW_DB        (source / landing)
  DEV_ENTECHLOG_PREP_DB       (staging / standardization)
  DEV_ENTECHLOG_DW_DB         (consumption - dim / fact / obt / semantic)

Warehouses
  DEV_ENTECHLOG_DBT_WH_XS     (service workload, per env)
  DEV_ENTECHLOG_CORTEX_WH_XS  (Cortex Analyst workload, per env)
  ALL_ENTECHLOG_ANALYST_WH_S  (user workload, shared across envs)

Resource Monitors
  DEV_ENTECHLOG_DBT_RM        (caps DBT workload across all sizes)
  ALL_ENTECHLOG_ANALYST_RM    (caps analyst spend across envs)

Access Roles (per DB, env-scoped)
  DEV_ENTECHLOG_RAW_RO_AR     DEV_ENTECHLOG_RAW_RW_AR
  DEV_ENTECHLOG_PREP_RO_AR    DEV_ENTECHLOG_PREP_RW_AR
  DEV_ENTECHLOG_DW_RO_AR      DEV_ENTECHLOG_DW_RW_AR

Functional Roles (no env - span envs via composed ARs)
  ENTECHLOG_ANALYST_FR
  ENTECHLOG_ENGINEER_FR
  ENTECHLOG_CORTEX_FR

Service-Functional Roles (per env, per tool)
  DEV_ENTECHLOG_DBT_SVC_FR
  DEV_ENTECHLOG_KAFKA_SVC_FR
  DEV_ENTECHLOG_SUPERSET_SVC_FR

Service users (per env, per tool - TYPE = SERVICE)
  DEV_ENTECHLOG_DBT_USER
  DEV_ENTECHLOG_KAFKA_USER
  DEV_ENTECHLOG_SUPERSET_USER
The grant chain:
ENGINEER_FR → DEV_RW_AR, STG_RW_AR, PRD_RW_AR  →  every table the team creates
ANALYST_FR  → DEV_RO_AR, STG_RO_AR, PRD_RO_AR
DBT_SVC_FR  → DEV_RAW_RO_AR + DEV_PREP_RW_AR + DEV_DW_RW_AR
Every layer changes for one reason: new DB? new ARs. New tool? new SVC_FR. New analyst? grant the FR. The blast radius of any one change stays tiny.
The chain above is the simplest version. Many teams tighten production by composing ENGINEER_FR from PRD_*_RO_AR instead of PRD_*_RW_AR, so humans read PRD and only the deploy tool’s PRD_..._SVC_FR writes to it.
The patterns are abstract until you apply them. Here are the requests I get most often.
USE ROLE SECURITYADMIN;
GRANT ROLE ENTECHLOG_ANALYST_FR TO USER "new.analyst@example.com";
-- FR already composes the DEV / STG / PRD RO_ARs. One statement, no per-table grants.
-- Need PRD-only access? See "Revoke an analyst's access to PRD only" below - that's a per-env FR.
USE ROLE SECURITYADMIN;

-- Vendor gets its own ad-hoc AR (NOT one of the standard per-DB ARs)
CREATE ROLE VENDOR_X_HUBSPOT_RO_AR;
GRANT USAGE  ON DATABASE DEV_ENTECHLOG_RAW_DB TO ROLE VENDOR_X_HUBSPOT_RO_AR;
GRANT USAGE  ON SCHEMA   DEV_ENTECHLOG_RAW_DB.HUBSPOT TO ROLE VENDOR_X_HUBSPOT_RO_AR;
GRANT SELECT ON ALL    TABLES IN SCHEMA DEV_ENTECHLOG_RAW_DB.HUBSPOT TO ROLE VENDOR_X_HUBSPOT_RO_AR;
GRANT SELECT ON FUTURE TABLES IN SCHEMA DEV_ENTECHLOG_RAW_DB.HUBSPOT TO ROLE VENDOR_X_HUBSPOT_RO_AR;

-- Wrap in an FR (with its own warehouse, so their spend is isolated) and grant to their user
CREATE ROLE VENDOR_X_FR;
GRANT ROLE VENDOR_X_HUBSPOT_RO_AR TO ROLE VENDOR_X_FR;
GRANT USAGE ON WAREHOUSE DEV_VENDOR_X_WH_XS TO ROLE VENDOR_X_FR;
GRANT ROLE VENDOR_X_FR TO ROLE SYSADMIN;
GRANT ROLE VENDOR_X_FR TO USER VENDOR_X_USER;
USE ROLE SYSADMIN;
CREATE DATABASE DEV_ENTECHLOG_MARKETING_DB;

USE ROLE SECURITYADMIN;
-- Two new ARs with FUTURE grants
CREATE ROLE DEV_ENTECHLOG_MARKETING_RO_AR;
CREATE ROLE DEV_ENTECHLOG_MARKETING_RW_AR;
GRANT USAGE ON DATABASE DEV_ENTECHLOG_MARKETING_DB TO ROLE DEV_ENTECHLOG_MARKETING_RO_AR;
GRANT USAGE ON DATABASE DEV_ENTECHLOG_MARKETING_DB TO ROLE DEV_ENTECHLOG_MARKETING_RW_AR;
-- (… FUTURE grants on schemas / tables / views …)

-- Wire them into existing FRs - the FR fans out the new access to all its users
GRANT ROLE DEV_ENTECHLOG_MARKETING_RO_AR TO ROLE ENTECHLOG_ANALYST_FR;
GRANT ROLE DEV_ENTECHLOG_MARKETING_RW_AR TO ROLE ENTECHLOG_ENGINEER_FR;
Every existing analyst now has read on the new DB. Every engineer has write. Zero per-user changes.
USE ROLE SECURITYADMIN;
CREATE ROLE DEV_ENTECHLOG_LOOKER_SVC_FR;
GRANT ROLE DEV_ENTECHLOG_DW_RO_AR TO ROLE DEV_ENTECHLOG_LOOKER_SVC_FR;
GRANT USAGE ON WAREHOUSE DEV_ENTECHLOG_LOOKER_WH_S TO ROLE DEV_ENTECHLOG_LOOKER_SVC_FR;
GRANT ROLE DEV_ENTECHLOG_LOOKER_SVC_FR TO ROLE SYSADMIN;

CREATE USER DEV_ENTECHLOG_LOOKER_USER
  TYPE              = SERVICE
  DEFAULT_ROLE      = DEV_ENTECHLOG_LOOKER_SVC_FR
  DEFAULT_WAREHOUSE = DEV_ENTECHLOG_LOOKER_WH_S;
GRANT ROLE DEV_ENTECHLOG_LOOKER_SVC_FR TO USER DEV_ENTECHLOG_LOOKER_USER;
-- (Register Looker's RSA public key on the user separately.)
-- Revoke the FR from the user. They keep DEV/STG access only if there are env-specific FRs.
-- With cross-env FRs, you instead revoke the PRD AR from the FR, which affects all analysts.
-- → If you need per-user env scoping, the flat pattern actually does it more cleanly.
-- → Most orgs handle "PRD-only access removal" via SSO/SCIM removing the user from the IDP group
--    that maps to the analyst FR.
This case is the strongest argument for per-env FRs (ENTECHLOG_PRD_ANALYST_FR vs ENTECHLOG_ANALYST_FR) if your access patterns are env-specific. Pick the model that matches your real revoke patterns.
If you already have a flat setup and want to move to AR / FR / SVC_FR without downtime:
SHOW GRANTS TO ROLE … + SNOWFLAKE.ACCOUNT_USAGE.GRANTS_TO_ROLES).FUTURE + ALL grants. Do not drop the existing roles yet.SYSADMIN.SHOW GRANTS OF ROLE … that every user has equivalent access through the new chain.Run this DB-by-DB; the two patterns coexist cleanly during the cutover.
A working DCM Projects demo that follows this naming (env-first databases, SVC_ deployer roles, one DCM database per team per env) is available in the snowflake-examples / snow-infra / dcm repo, and walked through in How to manage Snowflake infrastructure as code with DCM Projects. A thin platform layer creates each team’s deployer role, warehouse and DCM database and hands over ownership; each team then declares its own databases, schemas, tables, views and dynamic tables. The AR / FR / SVC_FR layer is documented there but left for teams to declare, since future grants need one of the MANAGE GRANTS workarounds above.
Account-level:
  USER (human)         [EMAIL]                                   → user@example.com
  USER (service)       [ENV]_[PROJECT]_[APP]_USER                → DEV_ENTECHLOG_DBT_USER
  ROLE (flat)          [PROJECT]_[ROLE]_ROLE                     → ENTECHLOG_ANALYST_ROLE
  ROLE (AR)            [ENV]_[PROJECT]_[LAYER]_RO_AR / _RW_AR    → DEV_ENTECHLOG_DW_RO_AR
  ROLE (FR)            [PROJECT]_[JOB]_FR                        → ENTECHLOG_ANALYST_FR
  ROLE (SVC_FR)        [ENV]_[PROJECT]_[TOOL]_SVC_FR             → DEV_ENTECHLOG_DBT_SVC_FR
  WAREHOUSE            [ENV]_[PROJECT]_[ROLE]_WH_[SIZE]          → DEV_ENTECHLOG_DBT_WH_XS
  WAREHOUSE (shared)   ALL_[PROJECT]_[ROLE]_WH_[SIZE]            → ALL_ENTECHLOG_ANALYST_WH_S
  RESOURCE MONITOR     [ENV]_[PROJECT]_[ROLE]_RM                 → DEV_ENTECHLOG_DBT_RM
  DATABASE             [ENV]_[PROJECT]_[LAYER]_DB                → DEV_ENTECHLOG_DW_DB
  STORAGE INTEGRATION  [NAME]_STORAGE_INTG                       → S3_RAW_STORAGE_INTG
  API INTEGRATION      [NAME]_API_INTG                           → GITHUB_API_INTG
  NOTIFICATION INTEG.  [NAME]_NOTIFY_INTG                        → MOCKAROO_SQS_NOTIFY_INTG
  NETWORK POLICY       [NAME]_NP                                 → CORP_VPN_NP
  COMPUTE POOL         [ENV]_[PROJECT]_[NAME]_POOL               → DEV_ENTECHLOG_ML_POOL
  SHARE (outbound)     [PROJECT]_[CONSUMER]_SHARE                → ENTECHLOG_PARTNER_X_SHARE

Schema-level:
  SCHEMA               [DATA_GROUPING]                           → HUBSPOT, DIM, FACT, STAGING
  TABLE / ICEBERG      [NAME]                                    → DEVICE
  VIEW                 [NAME]                                    → ACTIVE_DEVICE
  MATERIALIZED VIEW    [NAME]_MV                                 → DAILY_SALES_MV
  DYNAMIC TABLE        [NAME]_DT                                 → CUSTOMER_ORDERS_DT
  EXTERNAL TABLE       [NAME]_EXT                                → S3_EVENTS_EXT
  SEMANTIC VIEW        [NAME]_SV                                 → ORDER_STATS_SV
  FILE FORMAT          [NAME]_[FORMAT]_FF                        → MOCKAROO_XML_FF
  STAGE                [NAME]_[TYPE]_STG                         → MOCKAROO_S3_STG
  SNOWPIPE             [NAME]_PIPE                               → MOCKAROO_PIPE
  STREAM               [NAME]_STREAM                             → MOCKAROO_STREAM
  TASK                 [NAME]_TASK                               → MOCKAROO_TASK
  ALERT                [NAME]_ALERT                              → PIPE_FAILURE_ALERT
  STORED PROC          [NAME]_SP                                 → MOCKAROO_SP
  UDF / UDTF           [NAME]_UDF / _UDTF                        → NORMALIZE_PHONE_UDF
  STREAMLIT APP        [NAME]_APP                                → SALES_DASH_APP
  CORTEX AGENT         [NAME]_AGENT                              → SALES_AGENT
  TAG                  [NAME]_TAG                                → PII_TAG
  MASKING POLICY       [NAME]_MP                                 → EMAIL_MASK_MP
  ROW ACCESS POLICY    [NAME]_RAP                                → REGION_FILTER_RAP
  NETWORK RULE         [NAME]_NR                                 → CORP_VPN_NR
  PASSWORD POLICY      [NAME]_PP                                 → STRONG_PASSWORD_PP
  SESSION POLICY       [NAME]_SESS_POL                           → EXEC_SESSION_SESS_POL
  AUTH POLICY          [NAME]_AUTH_POL                           → SSO_ONLY_AUTH_POL
  DCM PROJECT          [ENV]_[PROJECT]_DCM_DB.PROJECTS.[SCOPE]   → DEV_ENTECHLOG_DCM_DB.PROJECTS.INFRA
If your team’s naming today is “whatever the person who built it picked”, start small:
I’d love to hear what your org’s naming ended up looking like - leave a comment with the patterns you’ve found work best, or the ones you wish you could change.
This blog represents my own viewpoints and not those of my employer. All product names, logos, and brands are the property of their respective owners.
Snowpipe is Snowflake’s continuous data ingestion service. Snowpipe loads data within minutes after files are …
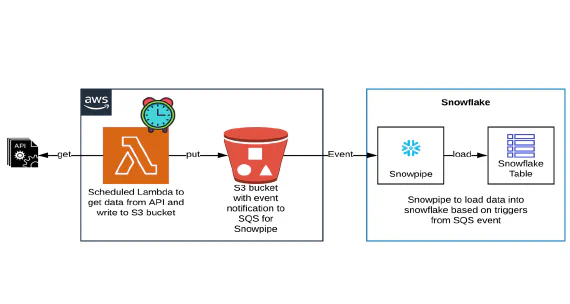
In this article, we will see how to get/pull data from an api, store in S3 and then stream the same data from S3 to …